Project FOMC29352 services include NGS sequencing of the V1V3 region of the 16S rRNA gene amplicons from the samples. First and foremost, please
download this report, as well as the sequence raw data from the download links provided below.
These links will expire after 60 days. We cannot guarantee the availability of your data after 60 days.
Full Bioinformatics analysis service was requested. We provide many analyses, starting from the raw sequence quality and noise filtering, pair reads merging, as well as chimera filtering for the sequences, using the
DADA2 denosing algorithm and pipeline.
We also provide many downstream analyses such as taxonomy assignment, alpha and beta diversity analyses, and differential abundance analysis.
For taxonomy assignment, most informative would be the taxonomy barplots. We provide an interactive barplots to show the relative abundance of microbes at different taxonomy levels (from Phylum to species) that you can choose.
If you specify which groups of samples you want to compare for differential abundance, we provide both ANCOM and LEfSe differential abundance analysis.
The samples were processed and analyzed with the ZymoBIOMICS® Service: Targeted
Metagenomic Sequencing (Zymo Research, Irvine, CA).
DNA Extraction: If DNA extraction was performed, the following DNA
extraction kit was used according to the manufacturer’s instructions:
☑
ZymoBIOMICS®-96 MagBead DNA Kit (Zymo Research, Irvine, CA)
☐
N/A (DNA Extraction Not Performed)
Elution Volume: 50µL
Additional Notes: NA
Targeted Library Preparation: The DNA samples were prepared for targeted
sequencing with the Quick-16S™ NGS Library Prep Kit (Zymo Research, Irvine, CA).
These primers were custom designed by Zymo Research to provide the best coverage
of the 16S gene while maintaining high sensitivity. The primer sets used in this project
are marked below:
☐
Quick-16S™ Primer Set V1-V2 (Zymo Research, Irvine, CA)
☑
Quick-16S™ Primer Set V1-V3 (Zymo Research, Irvine, CA)
☐
Quick-16S™ Primer Set V3-V4 (Zymo Research, Irvine, CA)
☐
Quick-16S™ Primer Set V4 (Zymo Research, Irvine, CA)
☐
Quick-16S™ Primer Set V6-V8 (Zymo Research, Irvine, CA)
Additional Notes: NA
The sequencing library was prepared using an innovative library preparation process in
which PCR reactions were performed in real-time PCR machines to control cycles and
therefore limit PCR chimera formation. The final PCR products were quantified with
qPCR fluorescence readings and pooled together based on equal molarity. The final
pooled library was cleaned up with the Select-a-Size DNA Clean & Concentrator™
(Zymo Research, Irvine, CA), then quantified with TapeStation® (Agilent Technologies,
Santa Clara, CA) and Qubit® (Thermo Fisher Scientific, Waltham, WA).
Control Samples: The ZymoBIOMICS® Microbial Community Standard (Zymo
Research, Irvine, CA) was used as a positive control for each DNA extraction, if
performed. The ZymoBIOMICS® Microbial Community DNA Standard (Zymo Research,
Irvine, CA) was used as a positive control for each targeted library preparation.
Negative controls (i.e. blank extraction control, blank library preparation control) were
included to assess the level of bioburden carried by the wet-lab process.
Sequencing: The final library was sequenced on Illumina® NextSeq 2000™ with a p1
(Illumina, Sand Diego, CA) reagent kit (600 cycles). The sequencing was performed
with 25% PhiX spike-in.
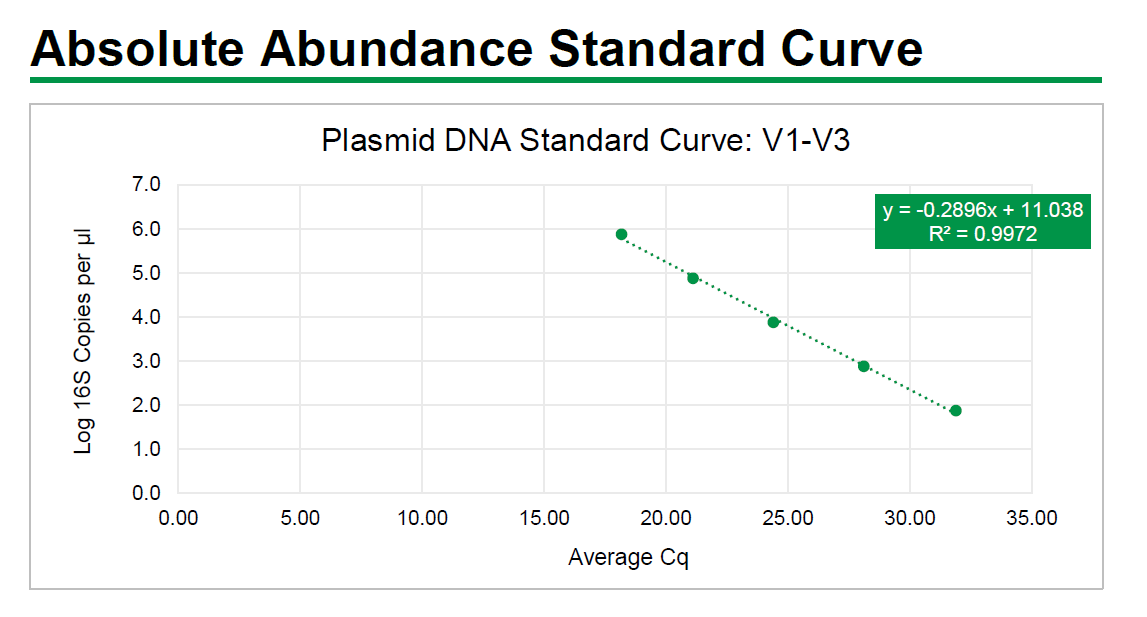
Absolute Abundance Quantification*: A quantitative real-time PCR was set up with a
standard curve. The standard curve was made with plasmid DNA containing one copy
of the 16S gene and one copy of the fungal ITS2 region prepared in 10-fold serial
dilutions. The primers used were the same as those used in Targeted Library
Preparation. The equation generated by the plasmid DNA standard curve was used to
calculate the number of gene copies in the reaction for each sample. The PCR input
volume (2 µl) was used to calculate the number of gene copies per microliter in each
DNA sample.
The number of genome copies per microliter DNA sample was calculated by dividing
the gene copy number by an assumed number of gene copies per genome. The value
used for 16S copies per genome is 4. The value used for ITS copies per genome is 200.
The amount of DNA per microliter DNA sample was calculated using an assumed
genome size of 4.64 x 10⁶ bp, the genome size of Escherichia coli, for 16S samples, or
an assumed genome size of 1.20 x 10⁷ bp, the genome size of Saccharomyces
cerevisiae, for ITS samples. This calculation is shown below:
Calculated Total DNA = Calculated Total Genome Copies × Assumed Genome Size (4.64 × 10⁶ bp) ×
Average Molecular Weight of a DNA bp (660 g/mole/bp) ÷ Avogadro’s Number (6.022 x 10²³/mole)
* Absolute Abundance Quantification is only available for 16S and ITS analyses.
The absolute abundance standard curve data can be viewed in Excel here:
The absolute abundance standard curve is shown below:
The complete report of your project, including all links in this report, can be downloaded by clicking the link provided below. The downloaded file is a compressed ZIP file and once unzipped, open the file “REPORT.html” (may only shown as "REPORT" in your computer) by double clicking it. Your default web browser will open it and you will see the exact content of this report.
Please download and save the file to your computer storage device. The download link will expire after 60 days upon your receiving of this report.
Complete report download link:
To view the report, please follow the following steps:
1.
Download the .zip file from the report link above.
2.
Extract all the contents of the downloaded .zip file to your desktop.
3.
Open the extracted folder and find the "REPORT.html" (may shown as only "REPORT").
4.
Open (double-clicking) the REPORT.html file. Your default browser will open the top age of the complete report. Within the
report, there are links to view all the analyses performed for the project.
The raw NGS sequence data is available for download with the link provided below. The data is a compressed ZIP file and can be unzipped to individual sequence files.
Since this is a Pac-Bio full-length (V1V9) 16S rRNA amplicon sequencing, raw sequences are available for download in a single compressed zip file in the download link below.
After unzipping, you will find individual sequence files for each of your samples with the file extension “*.fastq.gz”.
The files are in FASTQ format and are compressed. FASTQ format is a text-based data format for storing both a biological sequence
and its corresponding quality scores. Most sequence analysis software will be able to open them.
The Sample IDs associated with the fastq files are listed in the table below:
Sample ID
Original Sample ID
Read 1 File Name
Read 2 File Name
F29352.S100
original sample ID here
zr29352_100V1V3_R1.fastq.gz
zr29352_100V1V3_R2.fastq.gz
F29352.S101
original sample ID here
zr29352_101V1V3_R1.fastq.gz
zr29352_101V1V3_R2.fastq.gz
F29352.S102
original sample ID here
zr29352_102V1V3_R1.fastq.gz
zr29352_102V1V3_R2.fastq.gz
F29352.S103
original sample ID here
zr29352_103V1V3_R1.fastq.gz
zr29352_103V1V3_R2.fastq.gz
F29352.S104
original sample ID here
zr29352_104V1V3_R1.fastq.gz
zr29352_104V1V3_R2.fastq.gz
F29352.S105
original sample ID here
zr29352_105V1V3_R1.fastq.gz
zr29352_105V1V3_R2.fastq.gz
F29352.S106
original sample ID here
zr29352_106V1V3_R1.fastq.gz
zr29352_106V1V3_R2.fastq.gz
F29352.S107
original sample ID here
zr29352_107V1V3_R1.fastq.gz
zr29352_107V1V3_R2.fastq.gz
F29352.S108
original sample ID here
zr29352_108V1V3_R1.fastq.gz
zr29352_108V1V3_R2.fastq.gz
F29352.S109
original sample ID here
zr29352_109V1V3_R1.fastq.gz
zr29352_109V1V3_R2.fastq.gz
F29352.S010
original sample ID here
zr29352_10V1V3_R1.fastq.gz
zr29352_10V1V3_R2.fastq.gz
F29352.S110
original sample ID here
zr29352_110V1V3_R1.fastq.gz
zr29352_110V1V3_R2.fastq.gz
F29352.S111
original sample ID here
zr29352_111V1V3_R1.fastq.gz
zr29352_111V1V3_R2.fastq.gz
F29352.S112
original sample ID here
zr29352_112V1V3_R1.fastq.gz
zr29352_112V1V3_R2.fastq.gz
F29352.S113
original sample ID here
zr29352_113V1V3_R1.fastq.gz
zr29352_113V1V3_R2.fastq.gz
F29352.S114
original sample ID here
zr29352_114V1V3_R1.fastq.gz
zr29352_114V1V3_R2.fastq.gz
F29352.S115
original sample ID here
zr29352_115V1V3_R1.fastq.gz
zr29352_115V1V3_R2.fastq.gz
F29352.S116
original sample ID here
zr29352_116V1V3_R1.fastq.gz
zr29352_116V1V3_R2.fastq.gz
F29352.S117
original sample ID here
zr29352_117V1V3_R1.fastq.gz
zr29352_117V1V3_R2.fastq.gz
F29352.S118
original sample ID here
zr29352_118V1V3_R1.fastq.gz
zr29352_118V1V3_R2.fastq.gz
F29352.S119
original sample ID here
zr29352_119V1V3_R1.fastq.gz
zr29352_119V1V3_R2.fastq.gz
F29352.S011
original sample ID here
zr29352_11V1V3_R1.fastq.gz
zr29352_11V1V3_R2.fastq.gz
F29352.S120
original sample ID here
zr29352_120V1V3_R1.fastq.gz
zr29352_120V1V3_R2.fastq.gz
F29352.S121
original sample ID here
zr29352_121V1V3_R1.fastq.gz
zr29352_121V1V3_R2.fastq.gz
F29352.S122
original sample ID here
zr29352_122V1V3_R1.fastq.gz
zr29352_122V1V3_R2.fastq.gz
F29352.S123
original sample ID here
zr29352_123V1V3_R1.fastq.gz
zr29352_123V1V3_R2.fastq.gz
F29352.S124
original sample ID here
zr29352_124V1V3_R1.fastq.gz
zr29352_124V1V3_R2.fastq.gz
F29352.S125
original sample ID here
zr29352_125V1V3_R1.fastq.gz
zr29352_125V1V3_R2.fastq.gz
F29352.S126
original sample ID here
zr29352_126V1V3_R1.fastq.gz
zr29352_126V1V3_R2.fastq.gz
F29352.S127
original sample ID here
zr29352_127V1V3_R1.fastq.gz
zr29352_127V1V3_R2.fastq.gz
F29352.S128
original sample ID here
zr29352_128V1V3_R1.fastq.gz
zr29352_128V1V3_R2.fastq.gz
F29352.S129
original sample ID here
zr29352_129V1V3_R1.fastq.gz
zr29352_129V1V3_R2.fastq.gz
F29352.S012
original sample ID here
zr29352_12V1V3_R1.fastq.gz
zr29352_12V1V3_R2.fastq.gz
F29352.S130
original sample ID here
zr29352_130V1V3_R1.fastq.gz
zr29352_130V1V3_R2.fastq.gz
F29352.S131
original sample ID here
zr29352_131V1V3_R1.fastq.gz
zr29352_131V1V3_R2.fastq.gz
F29352.S132
original sample ID here
zr29352_132V1V3_R1.fastq.gz
zr29352_132V1V3_R2.fastq.gz
F29352.S133
original sample ID here
zr29352_133V1V3_R1.fastq.gz
zr29352_133V1V3_R2.fastq.gz
F29352.S134
original sample ID here
zr29352_134V1V3_R1.fastq.gz
zr29352_134V1V3_R2.fastq.gz
F29352.S135
original sample ID here
zr29352_135V1V3_R1.fastq.gz
zr29352_135V1V3_R2.fastq.gz
F29352.S136
original sample ID here
zr29352_136V1V3_R1.fastq.gz
zr29352_136V1V3_R2.fastq.gz
F29352.S137
original sample ID here
zr29352_137V1V3_R1.fastq.gz
zr29352_137V1V3_R2.fastq.gz
F29352.S138
original sample ID here
zr29352_138V1V3_R1.fastq.gz
zr29352_138V1V3_R2.fastq.gz
F29352.S139
original sample ID here
zr29352_139V1V3_R1.fastq.gz
zr29352_139V1V3_R2.fastq.gz
F29352.S013
original sample ID here
zr29352_13V1V3_R1.fastq.gz
zr29352_13V1V3_R2.fastq.gz
F29352.S140
original sample ID here
zr29352_140V1V3_R1.fastq.gz
zr29352_140V1V3_R2.fastq.gz
F29352.S141
original sample ID here
zr29352_141V1V3_R1.fastq.gz
zr29352_141V1V3_R2.fastq.gz
F29352.S142
original sample ID here
zr29352_142V1V3_R1.fastq.gz
zr29352_142V1V3_R2.fastq.gz
F29352.S014
original sample ID here
zr29352_14V1V3_R1.fastq.gz
zr29352_14V1V3_R2.fastq.gz
F29352.S015
original sample ID here
zr29352_15V1V3_R1.fastq.gz
zr29352_15V1V3_R2.fastq.gz
F29352.S016
original sample ID here
zr29352_16V1V3_R1.fastq.gz
zr29352_16V1V3_R2.fastq.gz
F29352.S017
original sample ID here
zr29352_17V1V3_R1.fastq.gz
zr29352_17V1V3_R2.fastq.gz
F29352.S018
original sample ID here
zr29352_18V1V3_R1.fastq.gz
zr29352_18V1V3_R2.fastq.gz
F29352.S019
original sample ID here
zr29352_19V1V3_R1.fastq.gz
zr29352_19V1V3_R2.fastq.gz
F29352.S001
original sample ID here
zr29352_1V1V3_R1.fastq.gz
zr29352_1V1V3_R2.fastq.gz
F29352.S020
original sample ID here
zr29352_20V1V3_R1.fastq.gz
zr29352_20V1V3_R2.fastq.gz
F29352.S021
original sample ID here
zr29352_21V1V3_R1.fastq.gz
zr29352_21V1V3_R2.fastq.gz
F29352.S022
original sample ID here
zr29352_22V1V3_R1.fastq.gz
zr29352_22V1V3_R2.fastq.gz
F29352.S023
original sample ID here
zr29352_23V1V3_R1.fastq.gz
zr29352_23V1V3_R2.fastq.gz
F29352.S024
original sample ID here
zr29352_24V1V3_R1.fastq.gz
zr29352_24V1V3_R2.fastq.gz
F29352.S025
original sample ID here
zr29352_25V1V3_R1.fastq.gz
zr29352_25V1V3_R2.fastq.gz
F29352.S026
original sample ID here
zr29352_26V1V3_R1.fastq.gz
zr29352_26V1V3_R2.fastq.gz
F29352.S027
original sample ID here
zr29352_27V1V3_R1.fastq.gz
zr29352_27V1V3_R2.fastq.gz
F29352.S028
original sample ID here
zr29352_28V1V3_R1.fastq.gz
zr29352_28V1V3_R2.fastq.gz
F29352.S029
original sample ID here
zr29352_29V1V3_R1.fastq.gz
zr29352_29V1V3_R2.fastq.gz
F29352.S002
original sample ID here
zr29352_2V1V3_R1.fastq.gz
zr29352_2V1V3_R2.fastq.gz
F29352.S030
original sample ID here
zr29352_30V1V3_R1.fastq.gz
zr29352_30V1V3_R2.fastq.gz
F29352.S031
original sample ID here
zr29352_31V1V3_R1.fastq.gz
zr29352_31V1V3_R2.fastq.gz
F29352.S032
original sample ID here
zr29352_32V1V3_R1.fastq.gz
zr29352_32V1V3_R2.fastq.gz
F29352.S033
original sample ID here
zr29352_33V1V3_R1.fastq.gz
zr29352_33V1V3_R2.fastq.gz
F29352.S034
original sample ID here
zr29352_34V1V3_R1.fastq.gz
zr29352_34V1V3_R2.fastq.gz
F29352.S035
original sample ID here
zr29352_35V1V3_R1.fastq.gz
zr29352_35V1V3_R2.fastq.gz
F29352.S036
original sample ID here
zr29352_36V1V3_R1.fastq.gz
zr29352_36V1V3_R2.fastq.gz
F29352.S037
original sample ID here
zr29352_37V1V3_R1.fastq.gz
zr29352_37V1V3_R2.fastq.gz
F29352.S038
original sample ID here
zr29352_38V1V3_R1.fastq.gz
zr29352_38V1V3_R2.fastq.gz
F29352.S039
original sample ID here
zr29352_39V1V3_R1.fastq.gz
zr29352_39V1V3_R2.fastq.gz
F29352.S003
original sample ID here
zr29352_3V1V3_R1.fastq.gz
zr29352_3V1V3_R2.fastq.gz
F29352.S040
original sample ID here
zr29352_40V1V3_R1.fastq.gz
zr29352_40V1V3_R2.fastq.gz
F29352.S041
original sample ID here
zr29352_41V1V3_R1.fastq.gz
zr29352_41V1V3_R2.fastq.gz
F29352.S042
original sample ID here
zr29352_42V1V3_R1.fastq.gz
zr29352_42V1V3_R2.fastq.gz
F29352.S043
original sample ID here
zr29352_43V1V3_R1.fastq.gz
zr29352_43V1V3_R2.fastq.gz
F29352.S044
original sample ID here
zr29352_44V1V3_R1.fastq.gz
zr29352_44V1V3_R2.fastq.gz
F29352.S045
original sample ID here
zr29352_45V1V3_R1.fastq.gz
zr29352_45V1V3_R2.fastq.gz
F29352.S046
original sample ID here
zr29352_46V1V3_R1.fastq.gz
zr29352_46V1V3_R2.fastq.gz
F29352.S047
original sample ID here
zr29352_47V1V3_R1.fastq.gz
zr29352_47V1V3_R2.fastq.gz
F29352.S048
original sample ID here
zr29352_48V1V3_R1.fastq.gz
zr29352_48V1V3_R2.fastq.gz
F29352.S049
original sample ID here
zr29352_49V1V3_R1.fastq.gz
zr29352_49V1V3_R2.fastq.gz
F29352.S004
original sample ID here
zr29352_4V1V3_R1.fastq.gz
zr29352_4V1V3_R2.fastq.gz
F29352.S050
original sample ID here
zr29352_50V1V3_R1.fastq.gz
zr29352_50V1V3_R2.fastq.gz
F29352.S051
original sample ID here
zr29352_51V1V3_R1.fastq.gz
zr29352_51V1V3_R2.fastq.gz
F29352.S052
original sample ID here
zr29352_52V1V3_R1.fastq.gz
zr29352_52V1V3_R2.fastq.gz
F29352.S053
original sample ID here
zr29352_53V1V3_R1.fastq.gz
zr29352_53V1V3_R2.fastq.gz
F29352.S054
original sample ID here
zr29352_54V1V3_R1.fastq.gz
zr29352_54V1V3_R2.fastq.gz
F29352.S055
original sample ID here
zr29352_55V1V3_R1.fastq.gz
zr29352_55V1V3_R2.fastq.gz
F29352.S056
original sample ID here
zr29352_56V1V3_R1.fastq.gz
zr29352_56V1V3_R2.fastq.gz
F29352.S057
original sample ID here
zr29352_57V1V3_R1.fastq.gz
zr29352_57V1V3_R2.fastq.gz
F29352.S058
original sample ID here
zr29352_58V1V3_R1.fastq.gz
zr29352_58V1V3_R2.fastq.gz
F29352.S059
original sample ID here
zr29352_59V1V3_R1.fastq.gz
zr29352_59V1V3_R2.fastq.gz
F29352.S005
original sample ID here
zr29352_5V1V3_R1.fastq.gz
zr29352_5V1V3_R2.fastq.gz
F29352.S060
original sample ID here
zr29352_60V1V3_R1.fastq.gz
zr29352_60V1V3_R2.fastq.gz
F29352.S061
original sample ID here
zr29352_61V1V3_R1.fastq.gz
zr29352_61V1V3_R2.fastq.gz
F29352.S062
original sample ID here
zr29352_62V1V3_R1.fastq.gz
zr29352_62V1V3_R2.fastq.gz
F29352.S063
original sample ID here
zr29352_63V1V3_R1.fastq.gz
zr29352_63V1V3_R2.fastq.gz
F29352.S064
original sample ID here
zr29352_64V1V3_R1.fastq.gz
zr29352_64V1V3_R2.fastq.gz
F29352.S065
original sample ID here
zr29352_65V1V3_R1.fastq.gz
zr29352_65V1V3_R2.fastq.gz
F29352.S066
original sample ID here
zr29352_66V1V3_R1.fastq.gz
zr29352_66V1V3_R2.fastq.gz
F29352.S067
original sample ID here
zr29352_67V1V3_R1.fastq.gz
zr29352_67V1V3_R2.fastq.gz
F29352.S068
original sample ID here
zr29352_68V1V3_R1.fastq.gz
zr29352_68V1V3_R2.fastq.gz
F29352.S069
original sample ID here
zr29352_69V1V3_R1.fastq.gz
zr29352_69V1V3_R2.fastq.gz
F29352.S006
original sample ID here
zr29352_6V1V3_R1.fastq.gz
zr29352_6V1V3_R2.fastq.gz
F29352.S070
original sample ID here
zr29352_70V1V3_R1.fastq.gz
zr29352_70V1V3_R2.fastq.gz
F29352.S071
original sample ID here
zr29352_71V1V3_R1.fastq.gz
zr29352_71V1V3_R2.fastq.gz
F29352.S072
original sample ID here
zr29352_72V1V3_R1.fastq.gz
zr29352_72V1V3_R2.fastq.gz
F29352.S073
original sample ID here
zr29352_73V1V3_R1.fastq.gz
zr29352_73V1V3_R2.fastq.gz
F29352.S074
original sample ID here
zr29352_74V1V3_R1.fastq.gz
zr29352_74V1V3_R2.fastq.gz
F29352.S075
original sample ID here
zr29352_75V1V3_R1.fastq.gz
zr29352_75V1V3_R2.fastq.gz
F29352.S076
original sample ID here
zr29352_76V1V3_R1.fastq.gz
zr29352_76V1V3_R2.fastq.gz
F29352.S077
original sample ID here
zr29352_77V1V3_R1.fastq.gz
zr29352_77V1V3_R2.fastq.gz
F29352.S078
original sample ID here
zr29352_78V1V3_R1.fastq.gz
zr29352_78V1V3_R2.fastq.gz
F29352.S079
original sample ID here
zr29352_79V1V3_R1.fastq.gz
zr29352_79V1V3_R2.fastq.gz
F29352.S007
original sample ID here
zr29352_7V1V3_R1.fastq.gz
zr29352_7V1V3_R2.fastq.gz
F29352.S080
original sample ID here
zr29352_80V1V3_R1.fastq.gz
zr29352_80V1V3_R2.fastq.gz
F29352.S081
original sample ID here
zr29352_81V1V3_R1.fastq.gz
zr29352_81V1V3_R2.fastq.gz
F29352.S082
original sample ID here
zr29352_82V1V3_R1.fastq.gz
zr29352_82V1V3_R2.fastq.gz
F29352.S083
original sample ID here
zr29352_83V1V3_R1.fastq.gz
zr29352_83V1V3_R2.fastq.gz
F29352.S084
original sample ID here
zr29352_84V1V3_R1.fastq.gz
zr29352_84V1V3_R2.fastq.gz
F29352.S085
original sample ID here
zr29352_85V1V3_R1.fastq.gz
zr29352_85V1V3_R2.fastq.gz
F29352.S086
original sample ID here
zr29352_86V1V3_R1.fastq.gz
zr29352_86V1V3_R2.fastq.gz
F29352.S087
original sample ID here
zr29352_87V1V3_R1.fastq.gz
zr29352_87V1V3_R2.fastq.gz
F29352.S088
original sample ID here
zr29352_88V1V3_R1.fastq.gz
zr29352_88V1V3_R2.fastq.gz
F29352.S089
original sample ID here
zr29352_89V1V3_R1.fastq.gz
zr29352_89V1V3_R2.fastq.gz
F29352.S008
original sample ID here
zr29352_8V1V3_R1.fastq.gz
zr29352_8V1V3_R2.fastq.gz
F29352.S090
original sample ID here
zr29352_90V1V3_R1.fastq.gz
zr29352_90V1V3_R2.fastq.gz
F29352.S091
original sample ID here
zr29352_91V1V3_R1.fastq.gz
zr29352_91V1V3_R2.fastq.gz
F29352.S092
original sample ID here
zr29352_92V1V3_R1.fastq.gz
zr29352_92V1V3_R2.fastq.gz
F29352.S093
original sample ID here
zr29352_93V1V3_R1.fastq.gz
zr29352_93V1V3_R2.fastq.gz
F29352.S094
original sample ID here
zr29352_94V1V3_R1.fastq.gz
zr29352_94V1V3_R2.fastq.gz
F29352.S095
original sample ID here
zr29352_95V1V3_R1.fastq.gz
zr29352_95V1V3_R2.fastq.gz
F29352.S096
original sample ID here
zr29352_96V1V3_R1.fastq.gz
zr29352_96V1V3_R2.fastq.gz
F29352.S097
original sample ID here
zr29352_97V1V3_R1.fastq.gz
zr29352_97V1V3_R2.fastq.gz
F29352.S098
original sample ID here
zr29352_98V1V3_R1.fastq.gz
zr29352_98V1V3_R2.fastq.gz
F29352.S099
original sample ID here
zr29352_99V1V3_R1.fastq.gz
zr29352_99V1V3_R2.fastq.gz
F29352.S009
original sample ID here
zr29352_9V1V3_R1.fastq.gz
zr29352_9V1V3_R2.fastq.gz
Please download and save the file to your computer storage device. The download link will expire after 60 days upon your receiving of this report.
DADA2 is a software package that models and corrects Illumina-sequenced amplicon errors [1].
DADA2 infers sample sequences exactly, without coarse-graining into OTUs,
and resolves differences of as little as one nucleotide. DADA2 identified more real variants
and output fewer spurious sequences than other methods.
DADA2’s advantage is that it uses more of the data. The DADA2 error model incorporates quality information,
which is ignored by all other methods after filtering. The DADA2 error model incorporates quantitative abundances,
whereas most other methods use abundance ranks if they use abundance at all.
The DADA2 error model identifies the differences between sequences, eg. A->C,
whereas other methods merely count the mismatches. DADA2 can parameterize its error model from the data itself,
rather than relying on previous datasets that may or may not reflect the PCR and sequencing protocols used in your study.
Callahan BJ, McMurdie PJ, Rosen MJ, Han AW, Johnson AJ, Holmes SP. DADA2: High-resolution sample inference from Illumina amplicon data. Nat Methods. 2016 Jul;13(7):581-3. doi: 10.1038/nmeth.3869. Epub 2016 May 23. PMID: 27214047; PMCID: PMC4927377.
Analysis Procedures:
DADA2 pipeline includes several tools for read quality control, including quality filtering, trimming, denoising, pair merging and chimera filtering. Below are the major processing steps of DADA2:
Step 1. Read trimming based on sequence quality
The quality of NGS Illumina sequences often decreases toward the end of the reads.
DADA2 allows to trim off the poor quality read ends in order to improve the error
model building and pair mergicing performance.
Step 2. Learn the Error Rates
The DADA2 algorithm makes use of a parametric error model (err) and every
amplicon dataset has a different set of error rates. The learnErrors method
learns this error model from the data, by alternating estimation of the error
rates and inference of sample composition until they converge on a jointly
consistent solution. As in many machine-learning problems, the algorithm must
begin with an initial guess, for which the maximum possible error rates in
this data are used (the error rates if only the most abundant sequence is
correct and all the rest are errors).
Step 3. Infer amplicon sequence variants (ASVs) based on the error model built in previous step. This step is also called sequence "denoising".
The outcome of this step is a list of ASVs that are the equivalent of oligonucleotides.
Step 4. Merge paired reads. If the sequencing products are read pairs, DADA2 will merge the R1 and R2 ASVs into single sequences.
Merging is performed by aligning the denoised forward reads with the reverse-complement of the corresponding
denoised reverse reads, and then constructing the merged “contig” sequences.
By default, merged sequences are only output if the forward and reverse reads overlap by
at least 12 bases, and are identical to each other in the overlap region (but these conditions can be changed via function arguments).
Step 5. Remove chimera.
The core dada method corrects substitution and indel errors, but chimeras remain. Fortunately, the accuracy of sequence variants
after denoising makes identifying chimeric ASVs simpler than when dealing with fuzzy OTUs.
Chimeric sequences are identified if they can be exactly reconstructed by
combining a left-segment and a right-segment from two more abundant “parent” sequences. The frequency of chimeric sequences varies substantially
from dataset to dataset, and depends on on factors including experimental procedures and sample complexity.
Results
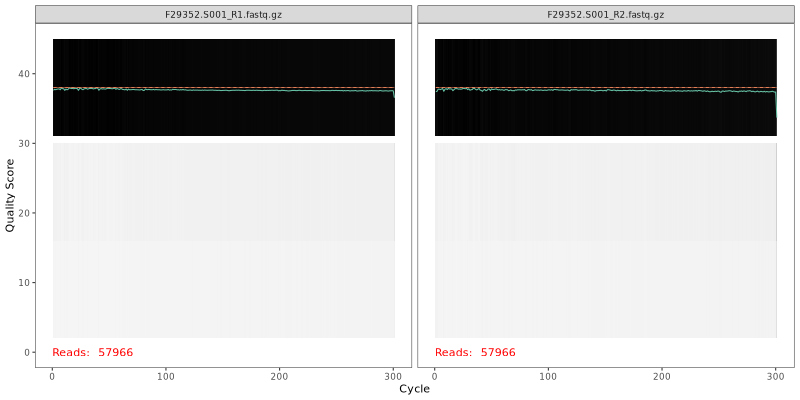
1. Read Quality Plots NGS sequence analaysis starts with visualizing the quality of the sequencing. Below are the quality plots of the first
sample for the R1 and R2 reads separately. In gray-scale is a heat map of the frequency of each quality score at each base position. The mean
quality score at each position is shown by the green line, and the quartiles of the quality score distribution by the orange lines.
The forward reads are usually of better quality. It is a common practice to trim the last few nucleotides to avoid less well-controlled errors
that can arise there. The trimming affects the downstream steps including error model building, merging and chimera calling. FOMC uses an empirical
approach to test many combinations of different trim length in order to achieve best final amplicon sequence variants (ASVs), see the next
section “Optimal trim length for ASVs”.
2. Optimal trim length for ASVs The final number of merged and chimera-filtered ASVs depends on the quality filtering (hence trimming) in the very beginning of the DADA2 pipeline.
In order to achieve highest number of ASVs, an empirical approach was used -
Create a random subset of each sample consisting of 5,000 R1 and 5,000 R2 (to reduce computation time)
Trim 10 bases at a time from the ends of both R1 and R2 up to 50 bases
For each combination of trimmed length (e.g., 300x300, 300x290, 290x290 etc), the trimmed reads are
subject to the entire DADA2 pipeline for chimera-filtered merged ASVs
The combination with highest percentage of the input reads becoming final ASVs is selected for the complete set of data
Below is the result of such operation, showing ASV percentages of total reads for all trimming combinations (1st Column = R1 lengths in bases; 1st Row = R2 lengths in bases):
R1/R2
301
291
281
271
261
251
301
56.00%
82.06%
82.17%
82.50%
82.27%
76.92%
291
56.04%
82.08%
82.20%
82.03%
76.68%
55.91%
281
56.19%
82.27%
81.92%
76.62%
55.92%
31.68%
271
56.29%
82.08%
76.62%
56.15%
31.79%
21.10%
261
55.96%
76.73%
56.25%
31.86%
21.18%
8.73%
251
50.47%
56.69%
32.21%
21.46%
8.87%
4.56%
Based on the above result, the trim length combination of R1 = 301 bases and R2 = 271 bases (highlighted red above), was chosen for generating final ASVs for all sequences.
This combination generated highest number of merged non-chimeric ASVs and was used for downstream analyses, if requested.
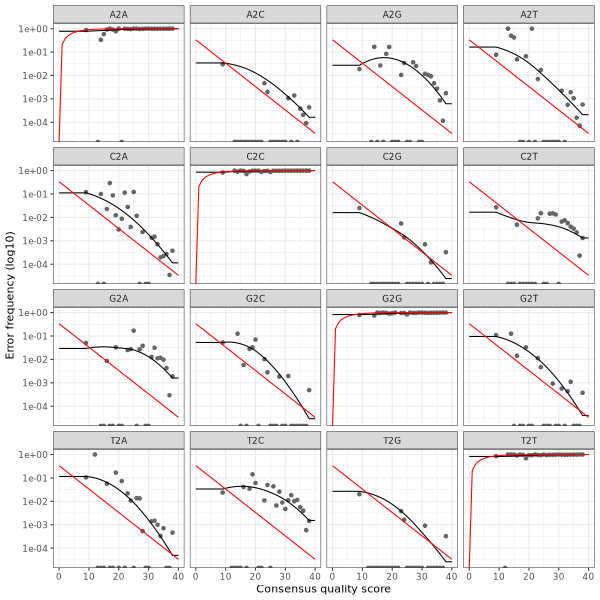
3. Error plots from learning the error rates
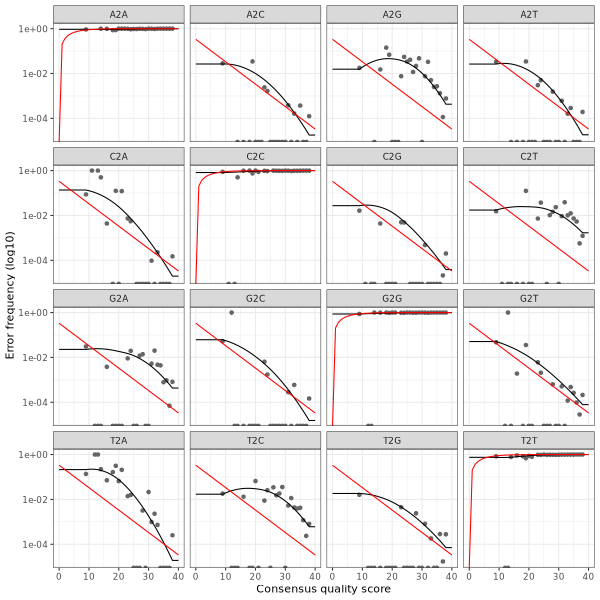
After DADA2 building the error model for the set of data, it is always worthwhile, as a sanity check if nothing else, to visualize the estimated error rates.
The error rates for each possible transition (A→C, A→G, …) are shown below. Points are the observed error rates for each consensus quality score.
The black line shows the estimated error rates after convergence of the machine-learning algorithm.
The red line shows the error rates expected under the nominal definition of the Q-score.
The ideal result would be the estimated error rates (black line) are a good fit to the observed rates (points), and the error rates drop
with increased quality as expected.
Forward Read R1 Error Plot
Reverse Read R2 Error Plot
The PDF version of these plots are available here:
4. DADA2 Result Summary The table below shows the summary of the DADA2 analysis,
tracking paired read counts of each samples for all the steps during DADA2 denoising process -
including end-trimming (filtered), denoising (denoisedF, denoisedF), pair merging (merged) and chimera removal (nonchim).
Sample ID
F29352.S001
F29352.S002
F29352.S003
F29352.S004
F29352.S005
F29352.S006
F29352.S007
F29352.S008
F29352.S009
F29352.S010
F29352.S011
F29352.S012
F29352.S013
F29352.S014
F29352.S015
F29352.S016
F29352.S017
F29352.S018
F29352.S019
F29352.S020
F29352.S021
F29352.S022
F29352.S023
F29352.S024
F29352.S025
F29352.S026
F29352.S027
F29352.S028
F29352.S029
F29352.S030
F29352.S031
F29352.S032
F29352.S033
F29352.S034
F29352.S035
F29352.S036
F29352.S037
F29352.S038
F29352.S039
F29352.S040
F29352.S041
F29352.S042
F29352.S043
F29352.S044
F29352.S045
F29352.S046
F29352.S047
F29352.S048
F29352.S049
F29352.S050
F29352.S051
F29352.S052
F29352.S053
F29352.S054
F29352.S055
F29352.S056
F29352.S057
F29352.S058
F29352.S059
F29352.S060
F29352.S061
F29352.S062
F29352.S063
F29352.S064
F29352.S065
F29352.S066
F29352.S067
F29352.S068
F29352.S069
F29352.S070
F29352.S071
F29352.S072
F29352.S073
F29352.S074
F29352.S075
F29352.S076
F29352.S077
F29352.S078
F29352.S079
F29352.S080
F29352.S081
F29352.S082
F29352.S083
F29352.S084
F29352.S085
F29352.S086
F29352.S087
F29352.S088
F29352.S089
F29352.S090
F29352.S091
F29352.S092
F29352.S093
F29352.S094
F29352.S095
F29352.S096
F29352.S097
F29352.S098
F29352.S099
F29352.S100
F29352.S101
F29352.S102
F29352.S103
F29352.S104
F29352.S105
F29352.S106
F29352.S107
F29352.S108
F29352.S109
F29352.S110
F29352.S111
F29352.S112
F29352.S113
F29352.S114
F29352.S115
F29352.S116
F29352.S117
F29352.S118
F29352.S119
F29352.S120
F29352.S121
F29352.S122
F29352.S123
F29352.S124
F29352.S125
F29352.S126
F29352.S127
F29352.S128
F29352.S129
F29352.S130
F29352.S131
F29352.S132
F29352.S133
F29352.S134
F29352.S135
F29352.S136
F29352.S137
F29352.S138
F29352.S139
F29352.S140
F29352.S141
F29352.S142
Row Sum
Percentage
input
57,966
88,726
83,189
50,835
65,939
65,461
74,174
48,917
58,205
70,533
64,702
65,867
65,021
47,835
69,893
62,710
59,721
62,512
50,773
65,042
64,539
64,396
69,352
65,999
67,180
48,418
53,621
77,455
90,195
67,286
69,230
67,427
61,737
67,978
62,555
67,211
70,945
59,295
64,346
51,314
69,214
67,073
60,699
75,811
106,066
83,411
65,474
50,658
84,960
98,720
80,767
65,608
78,796
106,444
82,202
63,255
70,753
85,215
61,615
70,094
74,182
90,135
78,919
65,779
95,445
69,326
88,010
97,279
86,837
78,170
61,178
63,001
77,547
78,150
91,749
78,922
71,038
63,566
96,525
49,870
76,542
110,890
68,703
93,433
73,448
80,548
67,210
76,353
77,376
73,641
57,936
77,890
71,499
69,803
71,965
84,019
62,741
64,173
76,431
76,800
90,396
64,198
80,102
71,125
73,024
75,898
82,655
91,158
82,637
92,618
82,294
75,357
63,508
79,408
72,272
74,164
83,718
87,037
85,210
71,593
55,227
74,613
67,235
55,666
72,094
68,683
73,138
64,764
58,582
58,572
78,074
87,106
70,747
89,520
77,674
62,900
72,130
65,713
68,128
60,840
84,561
75,390
10,302,093
100.00%
filtered
57,966
88,725
83,189
50,834
65,938
65,461
74,174
48,917
58,204
70,533
64,701
65,866
65,021
47,834
69,893
62,710
59,719
62,512
50,773
65,042
64,538
64,396
69,351
65,998
67,179
48,418
53,621
77,455
90,195
67,286
69,230
67,426
61,735
67,978
62,555
67,211
70,944
59,295
64,346
51,314
69,214
67,073
60,699
75,810
106,065
83,411
65,474
50,657
84,960
98,720
80,765
65,606
78,794
106,444
82,201
63,255
70,753
85,215
61,613
70,093
74,181
90,135
78,919
65,779
95,445
69,325
88,010
97,279
86,835
78,170
61,178
63,001
77,547
78,150
91,749
78,922
71,038
63,565
96,524
49,870
76,542
110,888
68,703
93,432
73,447
80,548
67,210
76,352
77,376
73,641
57,936
77,890
71,498
69,803
71,964
84,018
62,740
64,173
76,430
76,800
90,396
64,198
80,100
71,125
73,024
75,898
82,655
91,158
82,637
92,617
82,294
75,357
63,508
79,407
72,272
74,163
83,718
87,036
85,209
71,593
55,227
74,613
67,234
55,666
72,093
68,683
73,138
64,764
58,582
58,572
78,072
87,106
70,747
89,519
77,673
62,898
72,130
65,713
68,128
60,840
84,559
75,389
10,302,029
100.00%
denoisedF
57,294
88,019
82,503
50,291
65,220
64,951
73,344
48,450
57,558
69,755
63,890
65,167
64,095
47,452
69,352
62,394
58,797
61,878
50,329
64,336
63,798
63,706
68,496
65,422
66,414
47,921
53,005
76,810
89,737
66,674
68,618
66,648
60,805
67,271
62,039
66,449
70,102
58,873
63,979
50,610
68,482
66,427
60,196
75,219
105,593
82,726
64,727
50,029
84,031
97,938
80,018
64,811
78,143
105,782
81,291
62,605
69,803
84,335
61,105
69,409
73,287
89,246
78,209
65,155
94,230
68,699
87,155
96,357
86,222
77,647
60,312
62,351
76,982
77,762
91,406
78,249
70,456
63,073
95,953
49,341
75,829
110,534
68,093
92,933
73,046
80,229
66,660
75,565
76,780
72,892
57,395
77,222
71,068
69,010
71,432
83,330
62,296
63,286
76,098
76,373
90,110
63,908
79,667
70,323
72,027
75,352
81,945
90,335
82,080
92,291
81,821
74,660
63,232
78,933
71,652
73,732
83,336
86,467
84,543
70,861
54,865
74,137
66,608
55,257
71,561
67,977
72,499
64,060
58,107
58,078
77,629
86,449
69,832
89,307
76,636
62,369
71,688
65,110
67,527
60,540
84,403
74,652
10,213,851
99.14%
denoisedR
56,772
87,464
81,703
49,513
64,410
63,943
72,983
48,419
56,765
69,293
63,420
64,083
63,588
46,479
69,040
62,202
58,303
61,395
49,746
63,691
62,788
63,235
68,031
64,355
66,052
47,095
52,002
76,155
89,483
66,076
68,196
65,930
60,069
66,864
60,924
65,841
69,422
58,366
63,641
49,605
67,850
66,341
60,039
74,378
105,469
81,884
64,495
49,327
82,865
97,266
79,221
64,419
77,090
105,794
80,667
61,831
68,897
83,336
60,619
69,070
72,732
87,736
77,482
64,919
93,761
68,146
86,507
96,122
86,088
76,975
60,176
61,511
76,932
77,488
91,350
77,436
69,886
62,651
95,770
49,237
75,712
110,538
67,473
92,849
72,765
79,969
66,271
74,871
76,553
72,757
57,118
76,395
70,892
68,251
71,004
82,963
62,125
63,286
75,955
76,159
89,974
63,731
79,311
69,651
71,226
75,253
81,605
90,102
81,806
92,123
81,593
74,298
63,197
78,762
71,379
73,694
83,066
86,317
84,045
69,500
54,675
73,868
66,148
55,202
71,598
67,806
71,736
63,738
57,483
57,105
77,430
85,983
69,234
89,194
76,144
62,389
71,625
64,847
67,470
60,216
84,326
73,693
10,147,554
98.50%
merged
52,820
83,291
77,952
46,644
61,544
60,561
69,511
46,065
52,876
65,187
59,296
59,596
59,860
43,566
66,727
60,459
54,513
58,333
46,966
59,708
58,225
59,978
64,345
59,885
62,337
43,991
48,309
72,619
86,444
63,033
64,618
61,849
55,624
63,539
57,902
61,879
66,103
55,446
61,250
45,940
64,162
63,192
57,309
70,605
102,912
77,693
61,455
46,102
77,672
92,994
75,481
60,875
72,452
102,350
75,866
58,123
64,812
78,644
57,962
66,263
68,783
82,218
73,268
61,984
88,325
64,422
82,612
91,655
83,369
73,420
56,482
57,560
74,229
75,544
89,812
73,574
66,792
59,517
93,430
46,998
72,571
108,665
63,809
90,894
70,684
78,281
63,443
70,011
73,618
69,325
54,486
72,201
68,612
64,052
68,335
79,407
60,276
59,453
74,265
73,773
88,228
62,547
77,167
64,721
66,047
72,903
77,684
85,719
78,378
90,306
79,761
71,218
61,926
76,480
68,427
72,358
81,092
83,500
80,246
64,280
53,038
71,470
62,706
53,328
68,906
64,481
67,284
60,498
54,521
53,578
74,927
82,048
64,703
88,344
71,240
60,359
69,463
62,423
64,888
58,558
83,418
69,035
9,688,074
94.04%
nonchim
48,188
78,437
71,077
44,380
57,664
57,634
63,410
40,786
47,416
60,359
53,704
54,838
57,700
41,755
56,836
49,990
51,404
53,245
43,252
56,323
54,988
54,985
60,985
57,469
56,260
42,566
45,072
67,053
73,342
58,300
59,028
57,076
52,481
59,029
55,368
58,863
64,354
53,220
54,880
43,450
60,360
55,838
50,963
65,764
89,012
74,045
56,117
43,621
72,796
86,311
71,688
56,160
67,520
92,388
70,755
53,908
61,785
72,950
52,352
63,252
64,370
77,487
70,092
54,037
82,892
60,148
76,515
83,995
68,822
67,262
52,812
54,043
65,323
68,844
81,077
70,770
60,873
51,964
84,009
41,569
63,762
100,619
59,587
81,069
65,986
67,130
57,480
65,616
67,709
60,376
49,966
66,621
60,132
56,978
63,089
69,342
52,745
51,962
64,849
62,254
80,017
58,347
66,809
60,135
59,866
61,334
67,056
78,941
72,636
84,443
70,729
66,281
55,775
68,002
61,536
62,781
73,377
73,170
76,381
61,015
47,745
64,769
57,481
44,800
61,679
53,004
61,187
55,829
50,117
48,981
66,338
72,059
61,014
82,189
65,882
51,495
56,851
53,604
56,133
48,629
77,993
65,263
8,820,601
85.62%
This table can be downloaded as an Excel table below:
5. DADA2 Amplicon Sequence Variants (ASVs). A total of 16579 unique merged and chimera-free ASV sequences were identified, and their corresponding
read counts for each sample are available in the "ASV Read Count Table" with rows for the ASV sequences and columns for sample. This read count table can be used for
microbial profile comparison among different samples and the sequences provided in the table can be used to taxonomy assignment.
The species-level, open-reference 16S rRNA NGS reads taxonomy assignment pipeline
Version 20210310a
The close-reference taxonomy assignment of the ASV sequences using BLASTN is based on the algorithm published by Al-Hebshi et. al. (2015)[2].
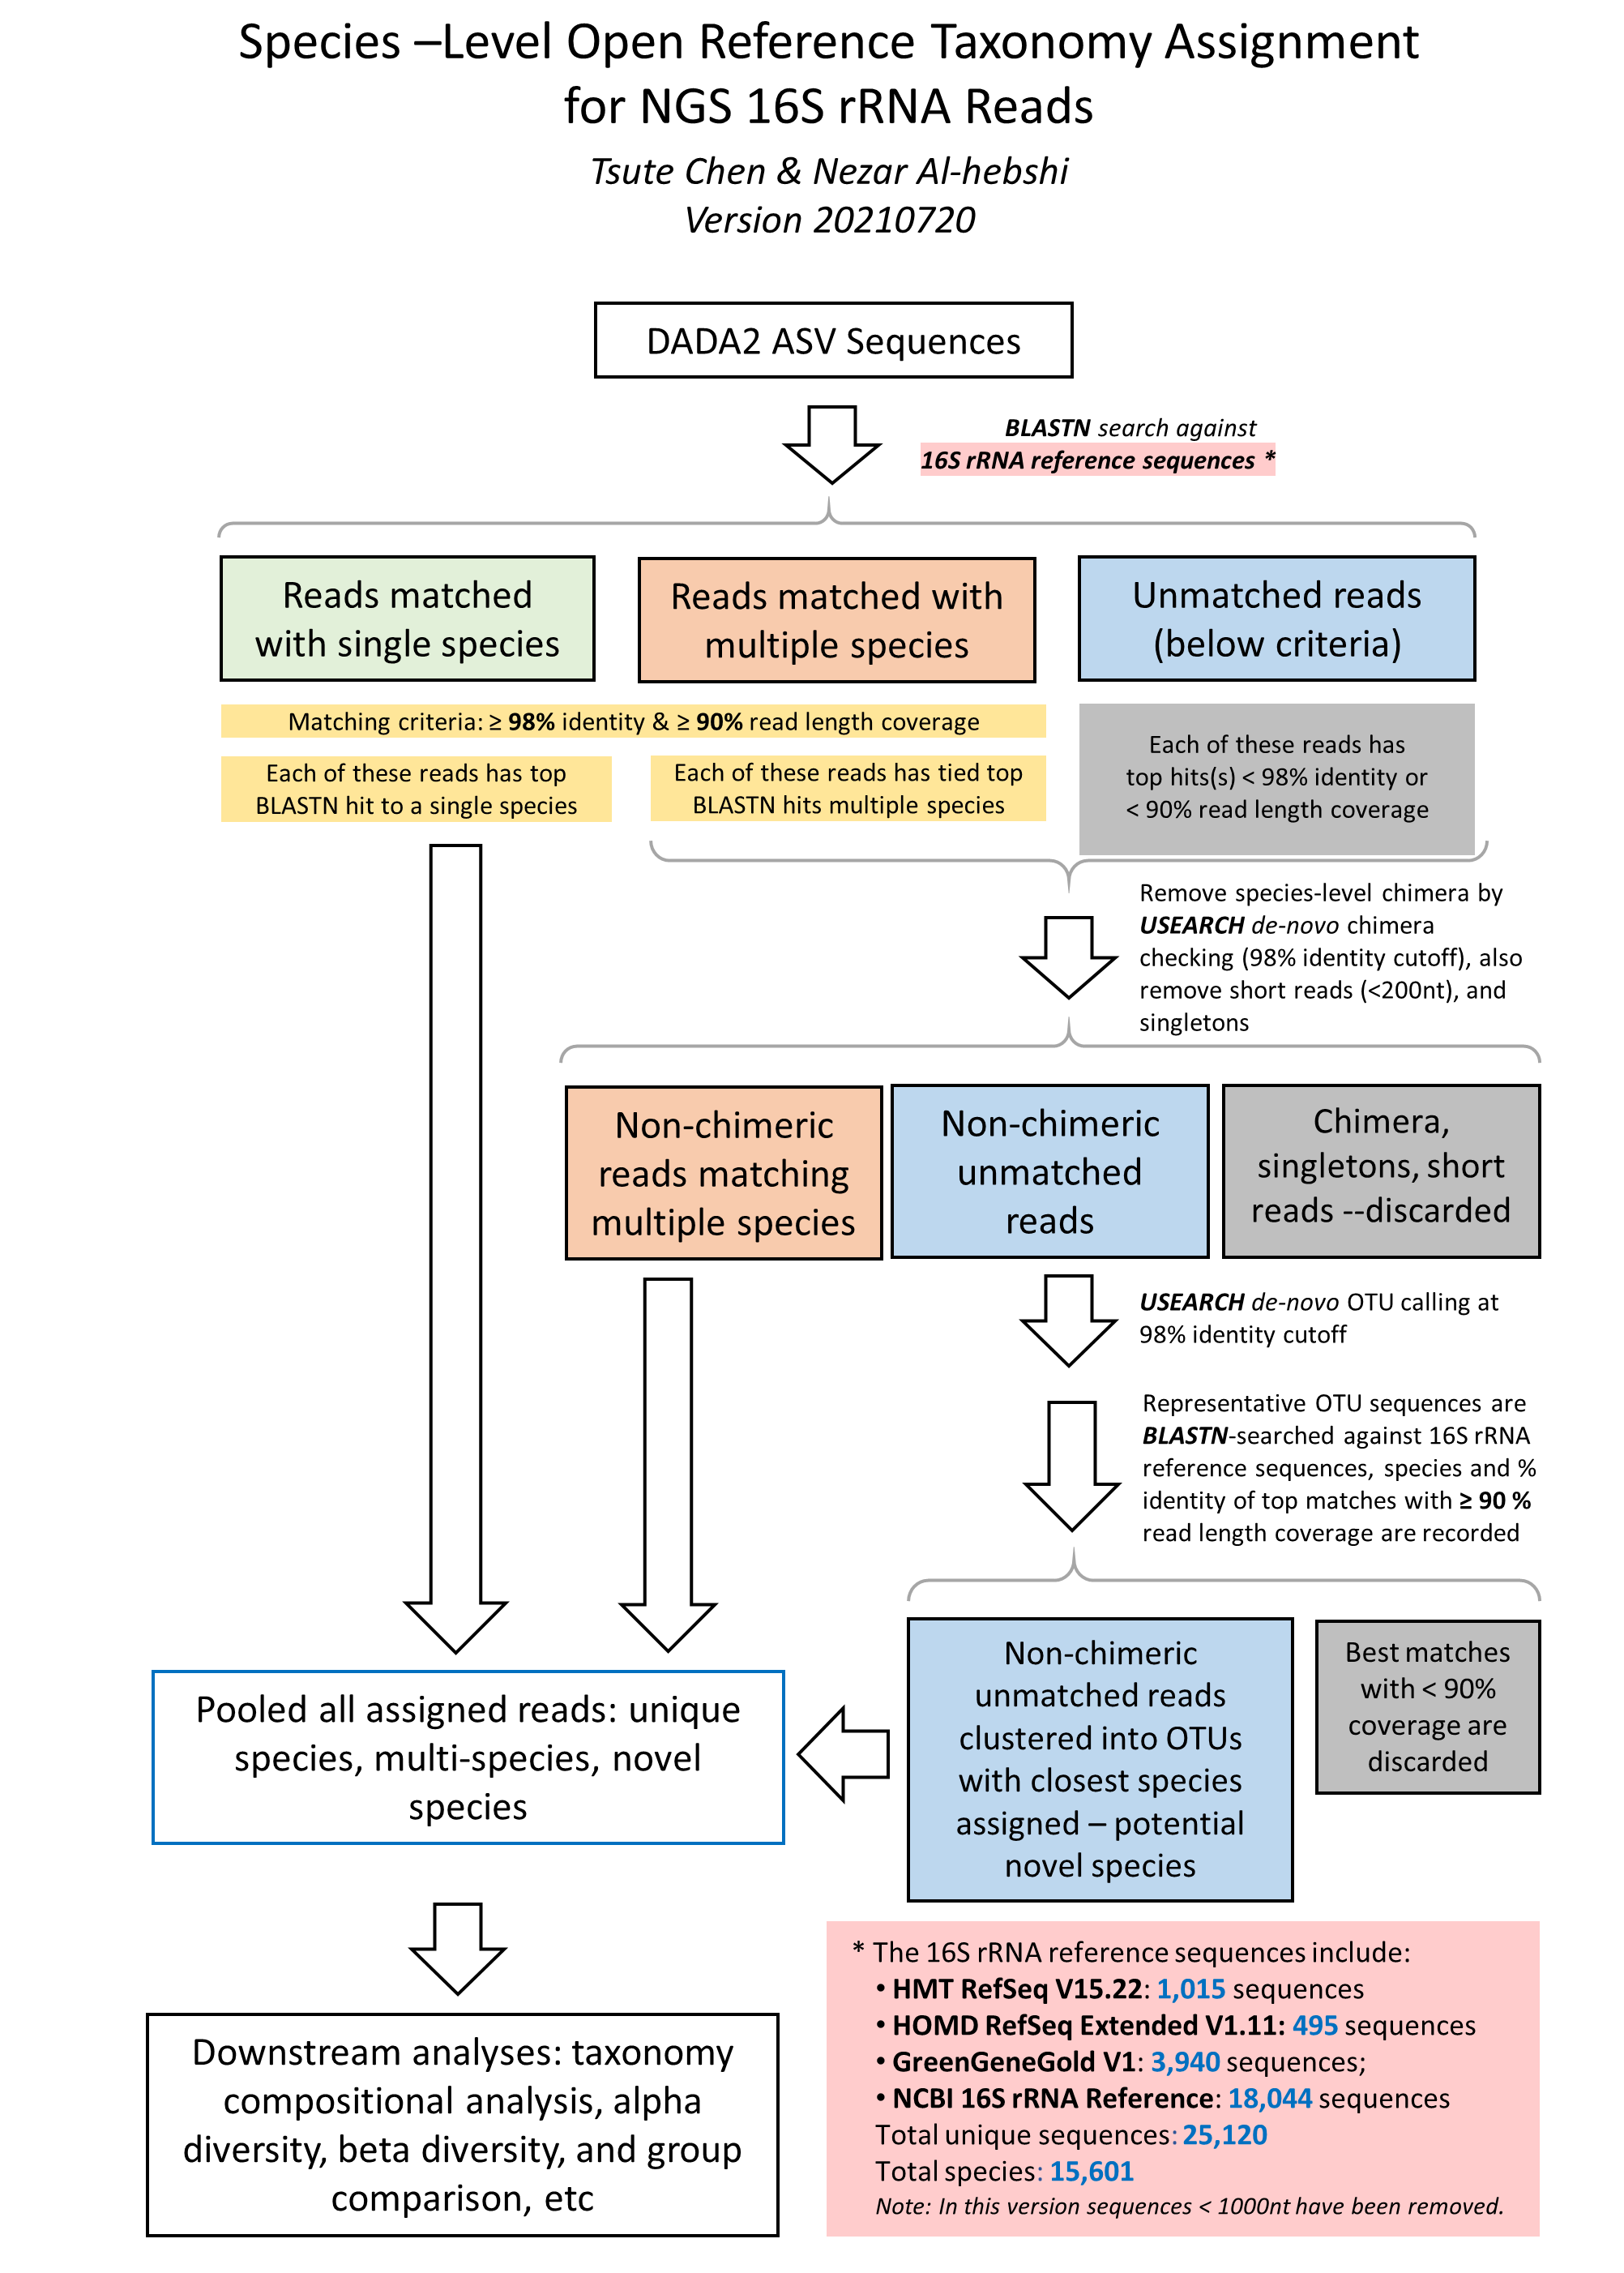
1. Raw sequences reads in FASTA format were BLASTN-searched against a combined set of 16S rRNA reference sequences - the FOMC 16S rRNA Reference Sequences version 20221029 (https://microbiome.forsyth.org/ftp/refseq/).
This set consists of the HOMD (version 15.22 http://www.homd.org/index.php?name=seqDownload&file&type=R ), Mouse Oral Microbiome Database (MOMD version 5.1 https://momd.org/ftp/16S_rRNA_refseq/MOMD_16S_rRNA_RefSeq/V5.1/),
and the NCBI 16S rRNA reference sequence set (https://ftp.ncbi.nlm.nih.gov/blast/db/16S_ribosomal_RNA.tar.gz).
These sequences were screened and combined to remove short sequences (<1000nt), chimera, duplicated and sub-sequences,
as well as sequences with poor taxonomy annotation (e.g., without species information).
This process resulted in 1,015 full-length 16S rRNA sequences from HOMD V15.22, 356 from MOMD V5.1, and 22,126 from NCBI, a total of 23,497 sequences.
Altogether these sequence represent a total of 17,035 oral and non-oral microbial species.
The NCBI BLASTN version 2.7.1+ (Zhang et al, 2000) [3] was used with the default parameters.
Reads with ≥ 98% sequence identity to the matched reference and ≥ 90% alignment length
(i.e., ≥ 90% of the read length that was aligned to the reference and was used to calculate
the sequence percent identity) were classified based on the taxonomy of the reference sequence
with highest sequence identity. If a read matched with reference sequences representing
more than one species with equal percent identity and alignment length, it was subject
to chimera checking with USEARCH program version v8.1.1861 (Edgar 2010). Non-chimeric reads with multi-species
best hits were considered valid and were assigned with a unique species
notation (e.g., spp) denoting unresolvable multiple species.
2. Unassigned reads (i.e., reads with < 98% identity or < 90% alignment length) were pooled together and reads < 200 bases were
removed. The remaining reads were subject to the de novo
operational taxonomy unit (OTU) calling and chimera checking using the USEARCH program version v8.1.1861 (Edgar 2010)[4].
The de novo OTU calling and chimera checking was done using 98% as the sequence identity cutoff, i.e., the species-level OTU.
The output of this step produced species-level de novo clustered OTUs with 98% identity.
Representative reads from each of the OTUs/species were then BLASTN-searched
against the same reference sequence set again to determine the closest species for
these potential novel species. These potential novel species were pooled together with the reads that were signed to specie-level in
the previous step, for down-stream analyses.
Reference:
Al-Hebshi NN, Nasher AT, Idris AM, Chen T. Robust species taxonomy assignment algorithm for 16S rRNA NGS reads: application
to oral carcinoma samples. J Oral Microbiol. 2015 Sep 29;7:28934. doi: 10.3402/jom.v7.28934. PMID: 26426306; PMCID: PMC4590409.
Zhang Z, Schwartz S, Wagner L, Miller W. A greedy algorithm for aligning DNA sequences. J Comput Biol. 2000 Feb-Apr;7(1-2):203-14. doi: 10.1089/10665270050081478. PMID: 10890397.
Edgar RC. Search and clustering orders of magnitude faster than BLAST.
Bioinformatics. 2010 Oct 1;26(19):2460-1. doi: 10.1093/bioinformatics/btq461. Epub 2010 Aug 12. PubMed PMID: 20709691.
3. Designations used in the taxonomy:
	1) Taxonomy levels are indicated by these prefixes:

	   k__: domain/kingdom
	   p__: phylum
	   c__: class
	   o__: order
	   f__: family
	   g__: genus
	   s__: species

	   Example:

	   k__Bacteria;p__Firmicutes;c__Clostridia;o__Clostridiales;f__Lachnospiraceae;g__Blautia;s__faecis

	2) Unique level identified – known species:

	   k__Bacteria;p__Firmicutes;c__Clostridia;o__Clostridiales;f__Lachnospiraceae;g__Roseburia;s__hominis

	   The above example shows some reads match to a single species (all levels are unique)

	3) Non-unique level identified – known species:

	   k__Bacteria;p__Firmicutes;c__Clostridia;o__Clostridiales;f__Lachnospiraceae;g__Roseburia;s__multispecies_spp123_3

	   The above example “s__multispecies_spp123_3” indicates certain reads equally match to 3 species of the
	   genus Roseburia; the “spp123” is a temporally assigned species ID.

	   k__Bacteria;p__Firmicutes;c__Clostridia;o__Clostridiales;f__Lachnospiraceae;g__multigenus;s__multispecies_spp234_5

	   The above example indicates certain reads match equally to 5 different species, which belong to multiple genera.;
	   the “spp234” is a temporally assigned species ID.

	4) Unique level identified – unknown species, potential novel species:

	   k__Bacteria;p__Firmicutes;c__Clostridia;o__Clostridiales;f__Lachnospiraceae;g__Roseburia;s__ hominis_nov_97%

	   The above example indicates that some reads have no match to any of the reference sequences with
	   sequence identity ≥ 98% and percent coverage (alignment length)  ≥ 98% as well. However this groups
	   of reads (actually the representative read from a de novo  OTU) has 96% percent identity to
	   Roseburia hominis, thus this is a potential novel species, closest to Roseburia hominis.
	   (But they are not the same species).

	5) Multiple level identified – unknown species, potential novel species:
	   k__Bacteria;p__Firmicutes;c__Clostridia;o__Clostridiales;f__Lachnospiraceae;g__Roseburia;s__ multispecies_sppn123_3_nov_96%

	   The above example indicates that some reads have no match to any of the reference sequences
	   with sequence identity ≥ 98% and percent coverage (alignment length)  ≥ 98% as well.
	   However this groups of reads (actually the representative read from a de novo  OTU)
	   has 96% percent identity equally to 3 species in Roseburia. Thus this is no single
	   closest species, instead this group of reads match equally to multiple species at 96%.
	   Since they have passed chimera check so they represent a novel species. “sppn123” is a
	   temporary ID for this potential novel species.
4. The taxonomy assignment algorithm is illustrated in this flow char below:
Read Taxonomy Assignment - Result Summary *
Code
Category
MPC=0% (>=1 read)
MPC=0.01%(>=876 reads)
A
Total reads
8,820,601
8,820,601
B
Total assigned reads
8,767,150
8,767,150
C
Assigned reads in species with read count < MPC
0
84,069
D
Assigned reads in samples with read count < 500
0
0
E
Total samples
142
142
F
Samples with reads >= 500
142
142
G
Samples with reads < 500
0
0
H
Total assigned reads used for analysis (B-C-D)
8,767,150
8,683,081
I
Reads assigned to single species
8,257,671
8,217,182
J
Reads assigned to multiple species
187,668
180,024
K
Reads assigned to novel species
321,811
285,875
L
Total number of species
1,233
405
M
Number of single species
535
338
N
Number of multi-species
55
13
O
Number of novel species
643
54
P
Total unassigned reads
53,451
53,451
Q
Chimeric reads
12,523
12,523
R
Reads without BLASTN hits
701
701
S
Others: short, low quality, singletons, etc.
40,227
40,227
A=B+P=C+D+H+Q+R+S
E=F+G
B=C+D+H
H=I+J+K
L=M+N+O
P=Q+R+S
* MPC = Minimal percent (of all assigned reads) read count per species, species with read count < MPC were removed.
* Samples with reads < 500 were removed from downstream analyses.
* The assignment result from MPC=0.1% was used in the downstream analyses.
Read Taxonomy Assignment - ASV Species-Level Read Counts Table
This table shows the read counts for each sample (columns) and each species identified based on the ASV sequences.
The downstream analyses were based on this table.
The species listed in the table has full taxonomy and a dynamically assigned species ID specific to this report.
When some reads match with the reference sequences of more than one species equally (i.e., same percent identiy and alignmnet coverage),
they can't be assigned to a particular species. Instead, they are assigned to multiple species with the species notaton
"s__multispecies_spp2_2". In this notation, spp2 is the dynamic ID assigned to these reads that hit multiple sequences and the "_2"
at the end of the notation means there are two species in the spp2.
You can look up which species are included in the multi-species assignment, in this table below:
Another type of notation is "s__multispecies_sppn2_2", in which the "n" in the sppn2 means it's a potential novel species because all the reads in this species
have < 98% idenity to any of the reference sequences. They were grouped together based on de novo OTU clustering at 98% identity cutoff. And then
a representative sequence was chosed to BLASTN search against the reference database to find the closest match (but will still be < 98%). This representative
sequence also matched equally to more than one species, hence the "spp" was given in the label.
In ecology, alpha diversity (α-diversity) is the mean species diversity in sites or habitats at a local scale.
The term was introduced by R. H. Whittaker[5][6] together with the terms beta diversity (β-diversity)
and gamma diversity (γ-diversity). Whittaker's idea was that the total species diversity in a landscape
(gamma diversity) is determined by two different things, the mean species diversity in sites or habitats
at a more local scale (alpha diversity) and the differentiation among those habitats (beta diversity).
Diversity measures are affected by the sampling depth. Rarefaction is a technique to assess species richness from the results of sampling. Rarefaction allows
the calculation of species richness for a given number of individual samples, based on the construction
of so-called rarefaction curves. This curve is a plot of the number of species as a function of the
number of samples. Rarefaction curves generally grow rapidly at first, as the most common species are found,
but the curves plateau as only the rarest species remain to be sampled [7].
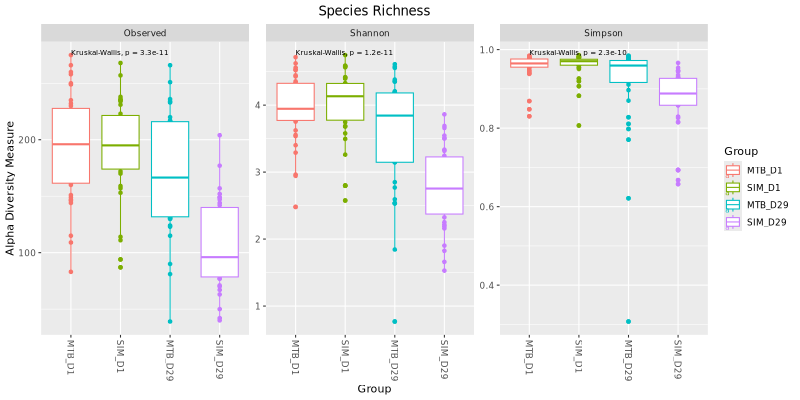
The two main factors taken into account when measuring diversity are richness and evenness.
Richness is a measure of the number of different kinds of organisms present in a particular area.
Evenness compares the similarity of the population size of each of the species present. There are
many different ways to measure the richness and evenness. These measurements are called "estimators" or "indices".
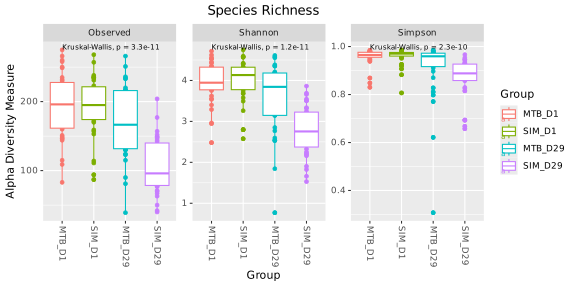
Below is a diversity of 3 commonly used indices showing the values for all the samples (dots) and in groups (boxes) at the species level.
Printed on each graph is the statistical significance p values of the difference between the groups.
The significance is calculated using either Kruskal-Wallis test or the Wilcoxon rank sum test, both are non-parametric methods (since
microbiome read count data are considered non-normally distributed) for testing
whether samples originate from the same distribution (i.e., no difference between groups). The Kruskal-Wallis test is used to compare three or more
independent groups to determine if there are statistically significant differences between their medians. The Wilcoxon Rank Sum test, also known as
the Mann-Whitney U test, is used to compare two independent groups to determine if there is a significant difference between their distributions.
The p-value is shown on the top of each graph. A p-value < 0.05 is considered statistically significant between/among the test groups.
Alpha Diversity Box Plots for All Groups - Species Level
Alpha Diversity Box Plots for Individual Comparisons at Species level
Beta diversity compares the similarity (or dissimilarity) of microbial profiles between different
groups of samples. There are many different similarity/dissimilarity metrics [8].
In general, they can be quantitative (using sequence abundance, e.g., Bray-Curtis or weighted UniFrac)
or binary (considering only presence-absence of sequences, e.g., binary Jaccard or unweighted UniFrac).
They can be even based on phylogeny (e.g., UniFrac metrics) or not (non-UniFrac metrics, such as Bray-Curtis, etc.).
For microbiome studies, species profiles of samples can be compared with the Bray-Curtis dissimilarity,
which is based on the count data type. The pair-wise Bray-Curtis dissimilarity matrix of all samples can then be
subject to either multi-dimensional scaling (MDS, also known as PCoA) or non-metric MDS (NMDS).
MDS/PCoA is a
scaling or ordination method that starts with a matrix of similarities or dissimilarities
between a set of samples and aims to produce a low-dimensional graphical plot of the data
in such a way that distances between points in the plot are close to original dissimilarities.
NMDS is similar to MDS, however it does not use the dissimilarities data, instead it converts them into
the ranks and use these ranks in the calculation.
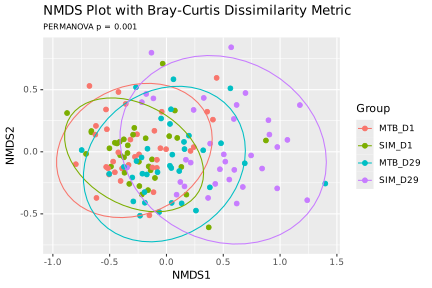
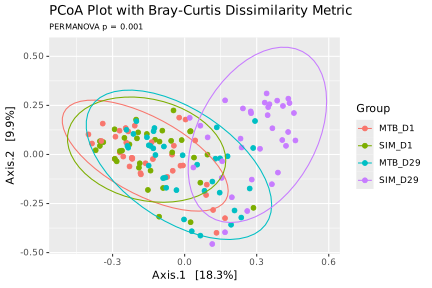
In our beta diversity analysis, Bray-Curtis dissimilarity matrix was first calculated and then plotted by the PCoA and
NMDS separately. Below are beta diveristy results for all groups together, at the Species level:
NMDS and PCoA Plots for All Groups - Species Level
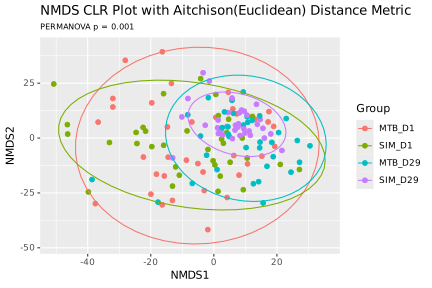
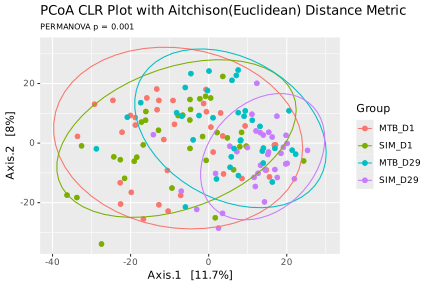
The above PCoA and NMDS plots are based on count data. The count data can also be transformed into centered log ratio (CLR)
for each species. The CLR data is no longer count data and cannot be used in Bray-Curtis dissimilarity calculation. Instead
CLR can be compared with Euclidean distances. When CLR data are compared by Euclidean distance, the distance is also called
Aitchison distance.
Below are the NMDS and PCoA plots of the Aitchison distances of the samples at the Species level:
NMDS and PCoA Plots for Individual Comparisons at Species level
16S rRNA next generation sequencing (NGS) generates a fixed number of reads that reflect the proportion of different
species in a sample, i.e., the relative abundance of species, instead of the absolute abundance.
In Mathematics, measurements involving probabilities, proportions, percentages, and ppm can all
be thought of as compositional data. This makes the microbiome read count data “compositional”
(Gloor et al, 2017). In general, compositional data represent parts of a whole which only
carry relative information [9].
The problem of microbiome data being compositional arises when comparing two groups of samples for
identifying “differentially abundant” species. A species with the same absolute abundance between two
conditions, its relative abundances in the two conditions (e.g., percent abundance) can become different
if the relative abundance of other species change greatly. This problem can lead to incorrect conclusion
in terms of differential abundance for microbial species in the samples.
When studying differential abundance (DA), the current better approach is to transform the read count
data into log ratio data. The ratios are calculated between read counts of all species in a sample to
a “reference” count (e.g., mean read count of the sample). The log ratio data allow the detection of DA
species without being affected by percentage bias mentioned above
In this report, a compositional DA analysis tool “ANCOM” (analysis of composition of microbiomes)
was used [10]. ANCOM transforms the count data into log-ratios and thus is more suitable for comparing
the composition of microbiomes in two or more populations. "ANCOM" generates a table of features with
W-statistics and whether the null hypothesis is rejected. The “W” is the W-statistic, or number of
features that a single feature is tested to be significantly different against. Hence the higher the "W"
the more statistical sifgnificant that a feature/species is differentially abundant.
Starting with version V1.2, we include the results of ANCOM-BC (Analysis of Compositions of
Microbiomes with Bias Correction) (Lin and Peddada 2020) [9]. ANCOM-BC is an updated version of "ANCOM" that:
(a) provides statistically valid test with appropriate p-values,
(b) provides confidence intervals for differential abundance of each taxon,
(c) controls the False Discovery Rate (FDR),
(d) maintains adequate power, and
(e) is computationally simple to implement.
The bias correction (BC) addresses a challenging problem of the bias introduced by differences in
the sampling fractions across samples. This bias has been a major hurdle in performing DA analysis of microbiome data.
ANCOM-BC estimates the unknown sampling fractions and corrects the bias induced by their differences among samples.
The absolute abundance data are modeled using a linear regression framework.
Starting with version V1.43, ANCOM-BC2 is used instead of ANCOM-BC, So that multiple pairwise directional test can be performed (if there are more than two gorups in a comparison).
When performing pairwise directional test, the mixed directional false discover rate (mdFDR) is taken into account. The mdFDR
is the combination of false discovery rate due to multiple testing, multiple pairwise comparisons, and directional tests within
each pairwise comparison. The mdFDR is adopted from (Guo, Sarkar, and Peddada 2010 [10]; Grandhi, Guo, and Peddada 2016 [11]). For more detail
explanation and additional features of ANCOM-BC2 please see author's documentation.
References:
Gloor GB, Macklaim JM, Pawlowsky-Glahn V, Egozcue JJ. Microbiome Datasets Are Compositional: And This Is Not Optional. Front Microbiol.
2017 Nov 15;8:2224. doi: 10.3389/fmicb.2017.02224. PMID: 29187837; PMCID: PMC5695134.
Mandal S, Van Treuren W, White RA, Eggesbø M, Knight R, Peddada SD. Analysis of composition of
microbiomes: a novel method for studying microbial composition. Microb Ecol Health Dis.
2015 May 29;26:27663. doi: 10.3402/mehd.v26.27663. PMID: 26028277; PMCID: PMC4450248.
Lin H, Peddada SD. Analysis of compositions of microbiomes with bias correction.
Nat Commun. 2020 Jul 14;11(1):3514. doi: 10.1038/s41467-020-17041-7.
PMID: 32665548; PMCID: PMC7360769.
Guo W, Sarkar SK, Peddada SD. Controlling false discoveries in multidimensional directional decisions, with applications to gene expression data on ordered categories. Biometrics. 2010 Jun;66(2):485-92. doi: 10.1111/j.1541-0420.2009.01292.x. Epub 2009 Jul 23. PMID: 19645703; PMCID: PMC2895927.
Grandhi A, Guo W, Peddada SD. A multiple testing procedure for multi-dimensional pairwise comparisons with application to gene expression studies. BMC Bioinformatics. 2016 Feb 25;17:104. doi: 10.1186/s12859-016-0937-5. PMID: 26917217; PMCID: PMC4768411.
"ALDEx2 is a compositional data analysis tool designed to enhance the statistical analysis of high-throughput sequencing datasets,
including RNA-seq, ChIP-seq, 16S rRNA gene sequencing, metagenomic analysis, and selective growth experiments.
Despite the fundamental similarities in data structure across these various experimental designs—namely,
counts of sequencing reads mapped to numerous features—traditional data analysis methods
have remained disparate and non-transferable between experiment types.
ALDEx2 addresses this challenge by employing compositional data analysis methods from the physical and geological sciences,
which convert raw data into relative abundances. This transformation leads to analyses that are more robust and reproducible.
Utilizing Bayesian methods to infer technical and statistical errors, ALDEx2 has demonstrated its applicability and effectiveness
across diverse datasets. It accurately identifies differential abundance and the direction of changes in selective growth experiments,
aligns closely with leading tools in identifying differentially expressed genes in RNA-seq datasets,
and successfully distinguishes differential taxa in the Human Microbiome Project 16S rRNA gene abundance dataset."
In this paired-sample differential abundance test, ALDEx2 was used with the Wilcoxon rank-sum test to identify features at different taxonomy ranks (from Phylum to Species)
that are significantly differentially abundant between two conditions. p-values were adjusted using "Holm" or "Benjamini-Hochberg" (BH) method to control the false discovery rate (FDR).
The simplest but strict p-value adjustment method is the Bonferroni method in which the p-values are multiplied by the number of comparisons.
Both Holm (1979) and Benjamini & Hochberg (1995) ("BH" or its alias "fdr") provide less conservative corrections.
In the below ALDEx2 result folder, comparisons were done with these two adjustment methods. Also, analyses were done with and without "paired sample" options for comparison.
References:
Fernandes AD, Macklaim JM, Linn TG, Reid G, Gloor GB. ANOVA-like differential expression (ALDEx) analysis for mixed population RNA-Seq. PLoS One. 2013 Jul 2;8(7):e67019. doi: 10.1371/journal.pone.0067019. PMID: 23843979; PMCID: PMC3699591.
Fernandes AD, Reid JN, Macklaim JM, McMurrough TA, Edgell DR, Gloor GB. Unifying the analysis of high-throughput sequencing datasets: characterizing RNA-seq, 16S rRNA gene sequencing and selective growth experiments by compositional data analysis. Microbiome. 2014 May 5;2:15. doi: 10.1186/2049-2618-2-15. PMID: 24910773; PMCID: PMC4030730.
Bonferroni, C. E., Teoria statistica delle classi e calcolo delle probabilità, Pubblicazioni del R Istituto Superiore di Scienze Economiche e Commerciali di Firenze 1936
Holm, S. (1979). A simple sequentially rejective multiple test procedure. Scandinavian Journal of Statistics, 6, 65--70. http://www.jstor.org/stable/4615733.
Benjamini, Y., and Hochberg, Y. (1995). Controlling the false discovery rate: a practical and powerful approach to multiple testing. Journal of the Royal Statistical Society Series B, 57, 289--300. http://www.jstor.org/stable/2346101.
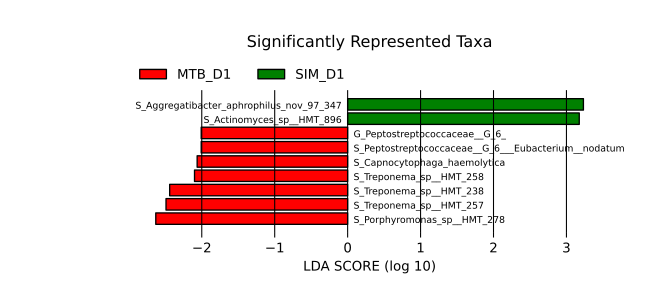
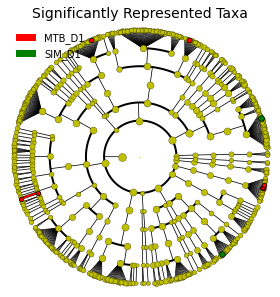
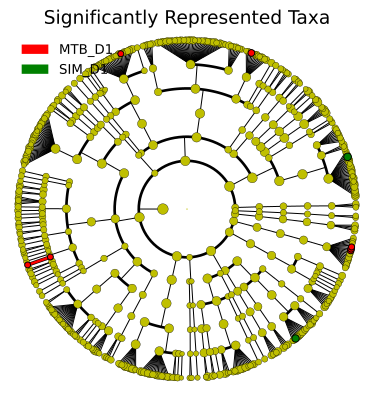
LEfSe (Linear Discriminant Analysis Effect Size) is an alternative method to find "organisms, genes, or
pathways that consistently explain the differences between two or more microbial communities" (Segata et al., 2011) [17].
Specifically, LEfSe uses rank-based Kruskal-Wallis (KW) sum-rank test to detect features with significant
differential (relative) abundance with respect to the class of interest. Since it is rank-based, instead of proportional based,
the differential species identified among the comparison groups is less biased (than percent abundance based).
Reference:
Segata N, Izard J, Waldron L, Gevers D, Miropolsky L, Garrett WS, Huttenhower C. Metagenomic biomarker discovery and explanation. Genome Biol. 2011 Jun 24;12(6):R60. doi: 10.1186/gb-2011-12-6-r60. PMID: 21702898; PMCID: PMC3218848.
1) Paired Differences - Paired difference testing and boxplots: This section uses QIIME2's "qiime longitudinal pairwise-differences" package to perform paired difference testing between samples from each subject. Sample
pairs may represent a typical intervention study (e.g., samples collected
pre- and post-treatment), paired samples from two different timepoints
(e.g., in a longitudinal study design), or identical samples receiving
different treatments. This action tests whether the change in a numeric
metadata value "metric" differs from zero and differs between groups (e.g.,
groups of subjects receiving different treatments), and produces boxplots of
paired difference distributions for each group. Note that "metric" can be
derived from a feature table or metadata.
2) Pairwise-distances - Paired pairwise distance testing and boxplots: This section uses QIIME2's "qiime longitudinal pairwise-distances" package to performs pairwise distance testing between sample pairs from each subject.
Sample pairs may represent a typical intervention study, e.g., samples
collected pre- and post-treatment; paired samples from two different
timepoints (e.g., in a longitudinal study design), or identical samples
receiving different two different treatments. This action tests whether the
pairwise distance between each subject pair differs between groups (e.g.,
groups of subjects receiving different treatments) and produces boxplots of
paired distance distributions for each group.
3) Volatility - Interactive control chart of longitudinal volatility: This section uses QIIME2's "qiime longitudinal volatility" package to generate an interactive control chart depicting the longitudinal volatility
of sample metadata and/or feature frequencies across time (as set using the
"state_column" parameter). Any numeric metadata column (and metadata-
transformable artifacts, e.g., alpha diversity results) can be plotted on
the y-axis, and are selectable using the "metric_column" selector. Metric
values are averaged to compare across any categorical metadata column using
the "group_column" selector. Longitudinal volatility for individual subjects
sampled over time is co-plotted as "spaghetti" plots if the
"individual_id_column" parameter is used. state_column will typically be a
measure of time, but any numeric metadata column can be used.
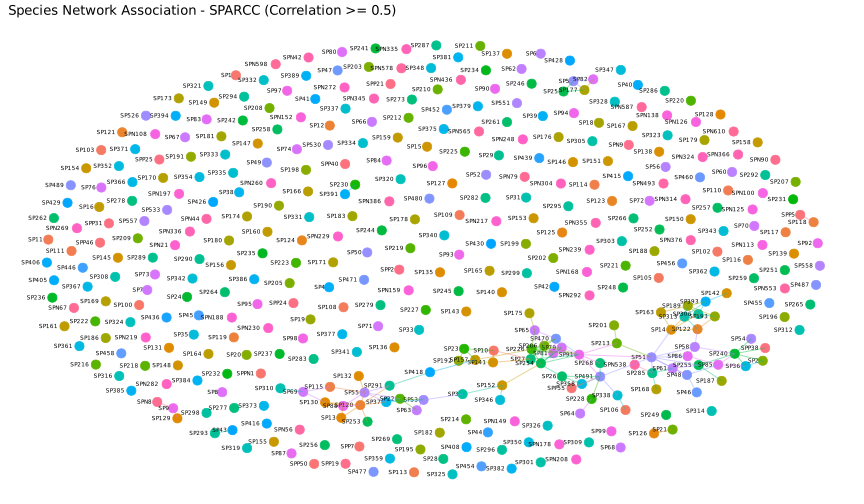
To analyze the co-occurrence or co-exclusion between microbial species among different samples, network correlation
analysis tools are usually used for this purpose. However, microbiome count data are compositional. If count data are normalized to the total number of counts in the
sample, the data become not independent and traditional statistical metrics (e.g., correlation) for the detection
of specie-species relationships can lead to spurious results. In addition, sequencing-based studies typically
measure hundreds of OTUs (species) on few samples; thus, inference of OTU-OTU association networks is severely
under-powered. We provide the network association result with SparCC (Sparse Correlations for Compositional data)(Friedman & Alm 2012), which
is a method for inferring correlations from compositional data. SparCC estimates the linear Pearson correlations between
the log-transformed components.
The results of this analysis are for research purpose only. They are not intended to diagnose, treat, cure, or prevent any disease. Forsyth and FOMC
are not responsible for use of information provided in this report outside the research area.